Where data takes root.
Build pipelines in notebooks, orchestrate workloads on the web, browse a unified catalog across AWS, GCP and Azure. Sown Data is the lakehouse and warehouse that grows with you, not against you.
Everything your data team needs, nothing they don't.
Sown unifies the four pieces every modern data team rebuilds from scratch: a notebook IDE, a pipeline orchestrator, a queryable warehouse, and a catalog. One control plane. Any cloud.
Polyglot notebooks
SQL, Python and Scala in the same notebook. Compile straight to a production pipeline with one click.
- DuckDB, Apache Spark™ and Polars engines
- Live collaboration, comments, branches
- Git-native, every cell is reviewable
Web orchestration
Schedule, retry, branch and backfill from the browser. SLAs, alerts, lineage-aware triggers, out of the box.
- Cron, event and webhook triggers
- Visual DAG with live run status
- PagerDuty, Slack, OpsGenie alerts
Unified catalog
Browse every table, view and stream across every cloud. Search, schemas, lineage and quality, all queryable from one place.
- Cross-cloud column-level lineage
- Faceted search with semantic tags
- Certified assets & PII tagging
Open warehouse
Iceberg-native. Bring your own storage. Query through Snowflake, BigQuery, Synapse, Trino™, or all of them.
- Apache Iceberg + Delta + Parquet
- BYO S3 / GCS / ADLS, your buckets
- No vendor lock-in. Ever.
Data quality & observability
Freshness, drift, schema and custom checks, declared next to the data and alerted before downstream notices.
- SLA tracking + auto-incident creation
- Drift detection on every refresh
- Quality scores per asset
Enterprise-ready
SSO, audit, region pinning and customer-managed keys. The boring parts that make security teams smile.
- Compliance requirements reviewed case-by-case
- Okta / Azure AD / Google SSO
- VPC-peered private deployments
Write it once. Ship it as a pipeline.
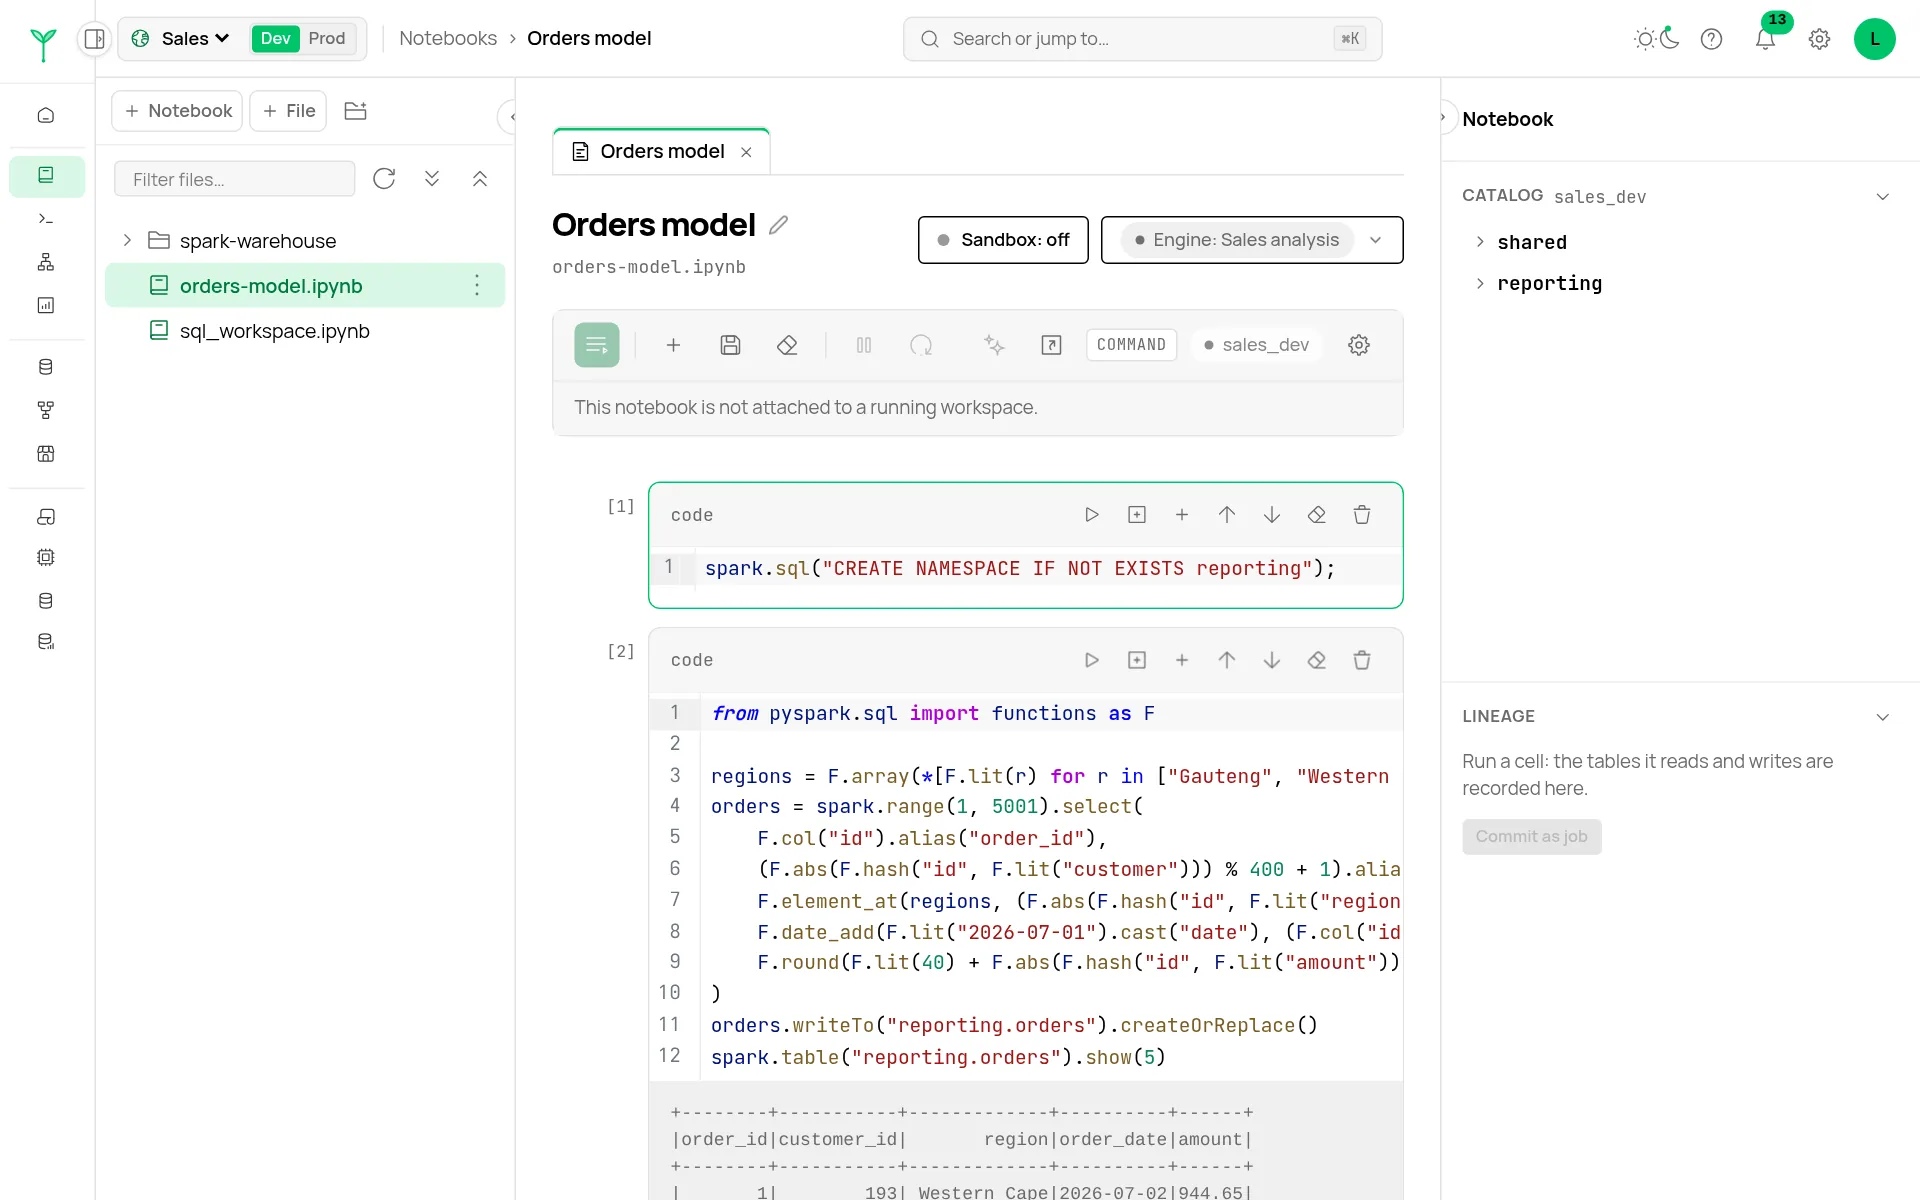
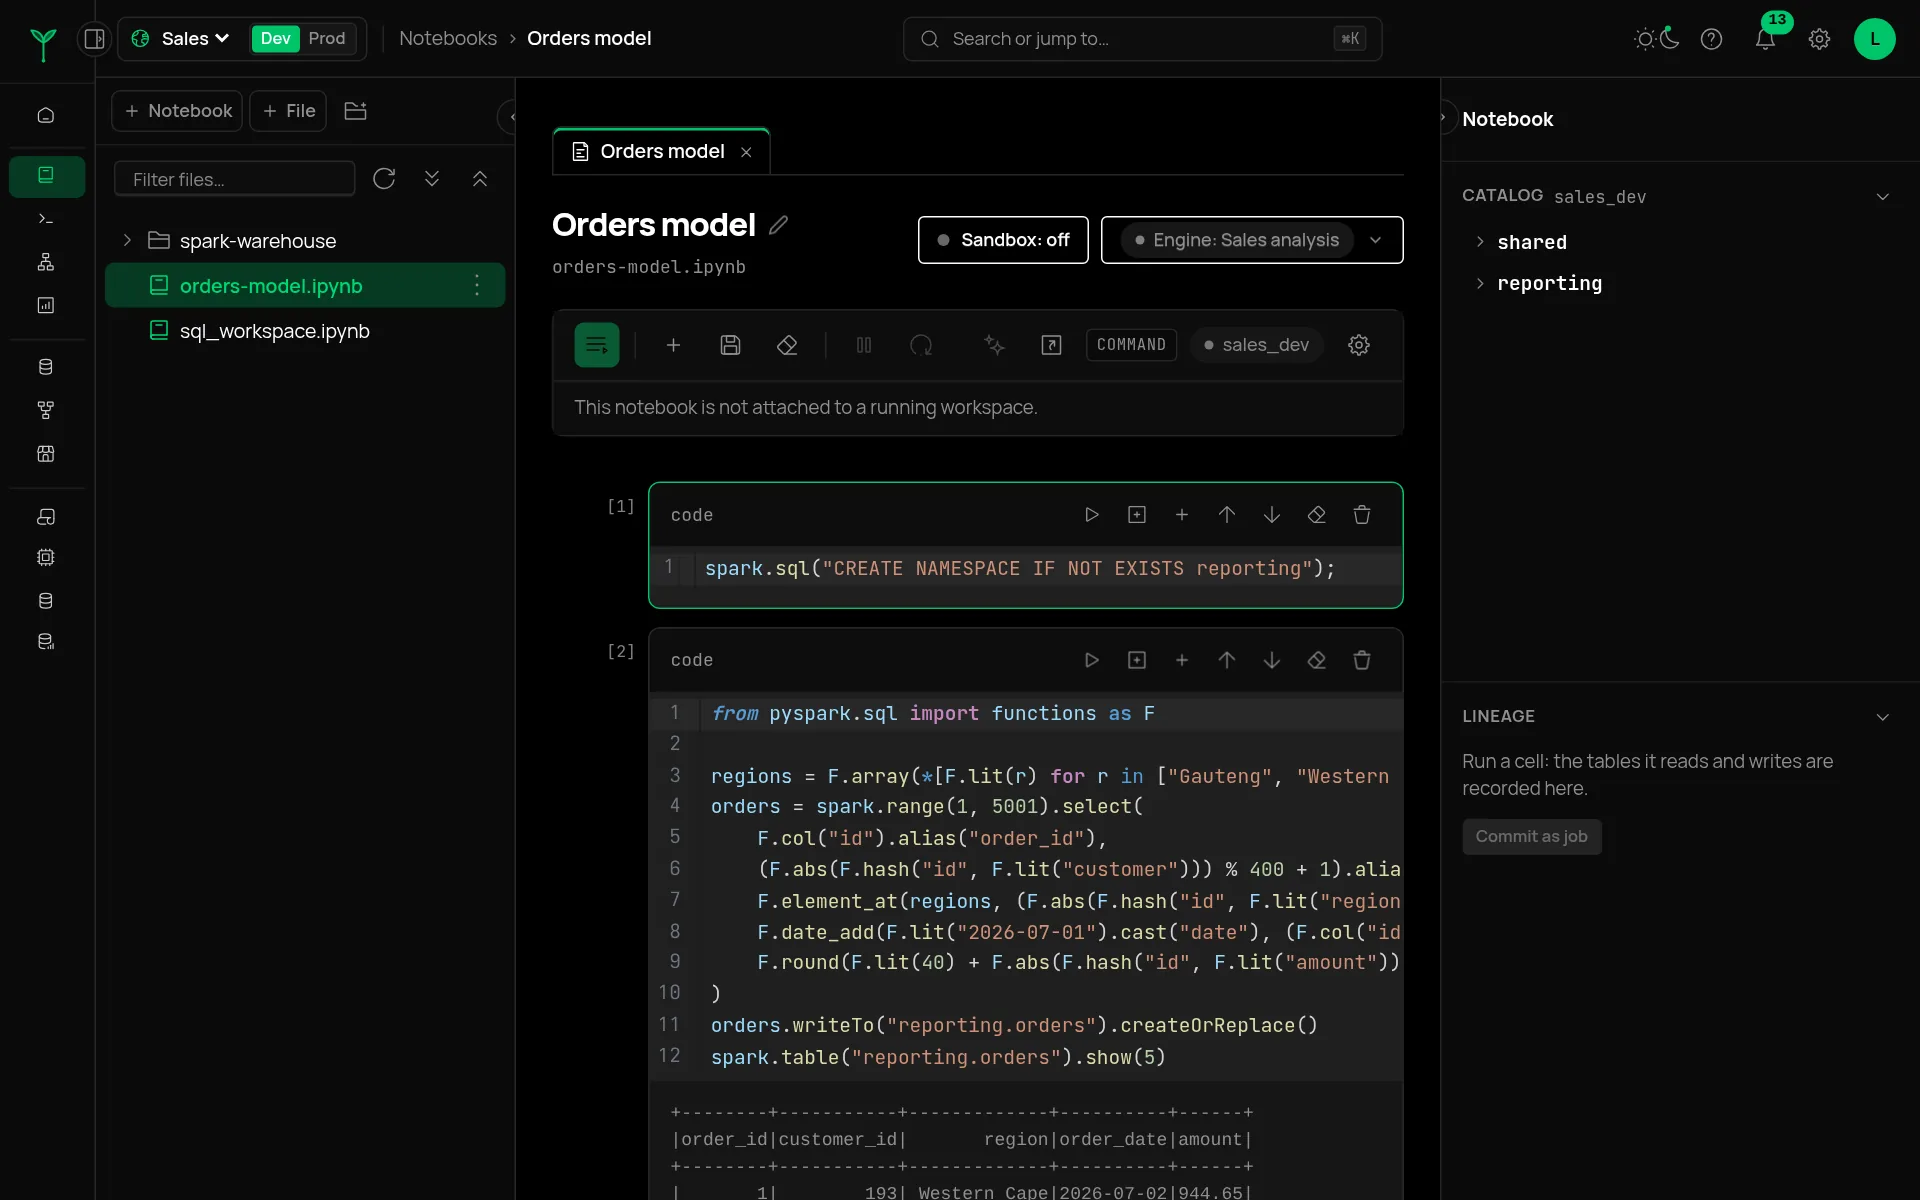
SQL and Python cells in one notebook. sd.publish() turns any cell's output into a versioned, scheduled, governed asset. No rewrite, no copy-paste.
- Reproducible. Every run is git-pinned with a content hash.
- Testable. Inline assertions become DQ checks in production.
- Observable. Runtime, rows scanned and cost, visible per cell.
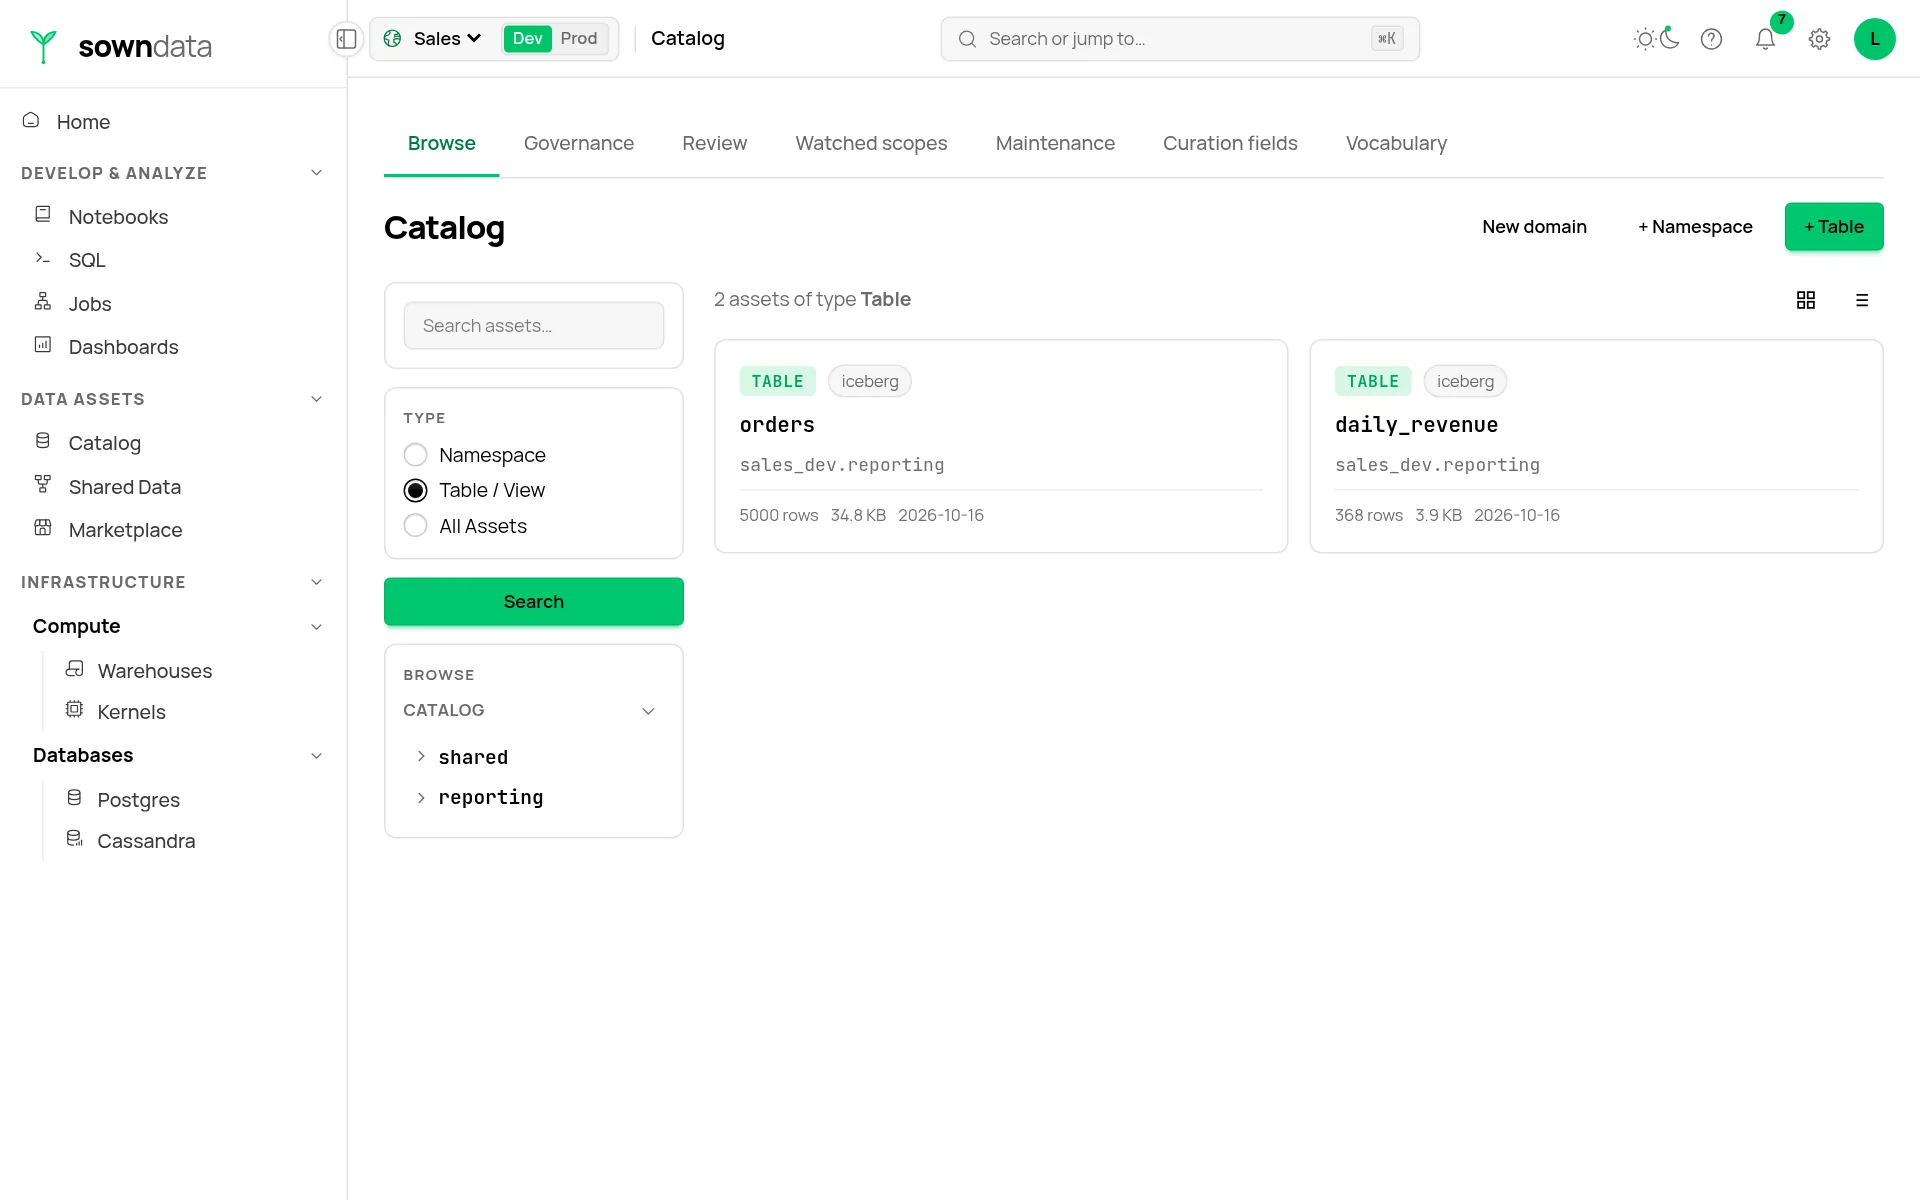
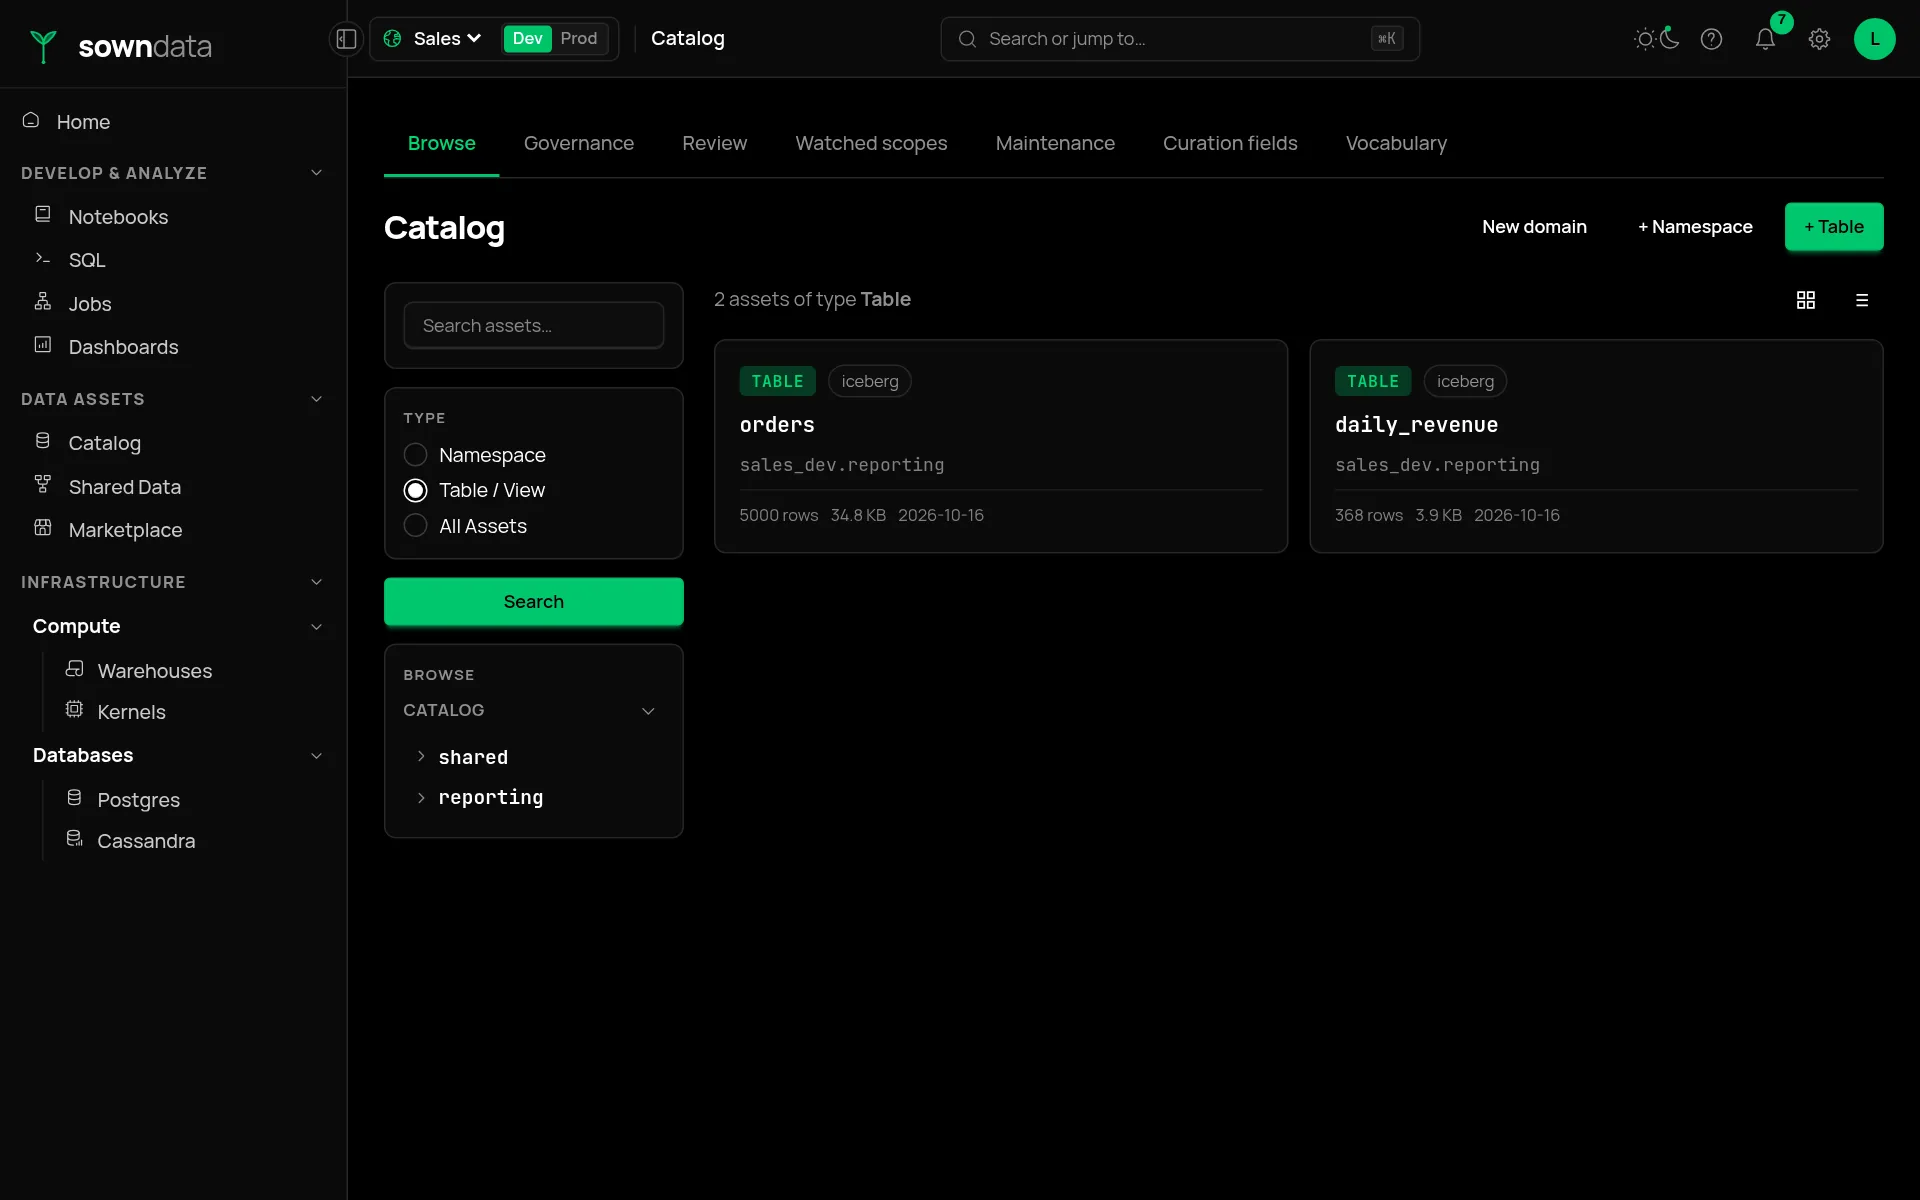
Find the table, then see whether to trust it.
Every namespace and table you can read in a domain's environment, in one list, read live from the catalog: schema, owner, snapshots, lineage, quality and who may read it. Query any of them from a notebook or a SQL warehouse.
- Lineage from the engine. Recorded as work runs, not inferred from code afterwards.
- Permissions on every table. Each grant, what it allows, and where it came from.
- PII found by profiling. Column shapes are scanned and tagged, and a person reviews each tag before it affects anything.
Your platform knows your data. Ask it anything.
An enterprise AI assistant is embedded across your workflows — not bolted on. Generate code, tune queries, troubleshoot failed jobs, and discover certified data assets using natural language.
From natural language to production PySpark.
Generate PySpark transformations, SQL queries, and Argo workflow specs from a prompt. Paste a slow query and receive refactored SQL, partition pruning optimizations, and explain-plan diagnostics. Ask about your data — get certified table references back.
- Code & SQL generation. Describe the transformation; get production-ready PySpark or SQL.
- Query tuning. Automated refactoring with partition pruning and broadcast hints.
- Job diagnostics. Analyzes driver logs, executor errors, and system metrics to pinpoint root causes with step-by-step fixes.
- Natural language discovery. "Which dataset contains active customer churn rates for Southern Africa?" returns a certified table reference instantly.
orders_hourly pipeline fail at stage 4?Fix: Increase Core NVMe from 500 GB → 1 TB in your compute profile, or enable
spark.shuffle.compress=true to reduce shuffle footprint by ~40%.
orders join query./*+ BROADCAST(dim_customer) */ hint (2.1 MB table), pushed WHERE region = 'ZA' before the join, and replaced SELECT * with explicit column projection. Estimated scan reduction: 74%.
Plant the seed today.
We will walk through your workloads and show what runs where.